Data Engineering
Enlyghten
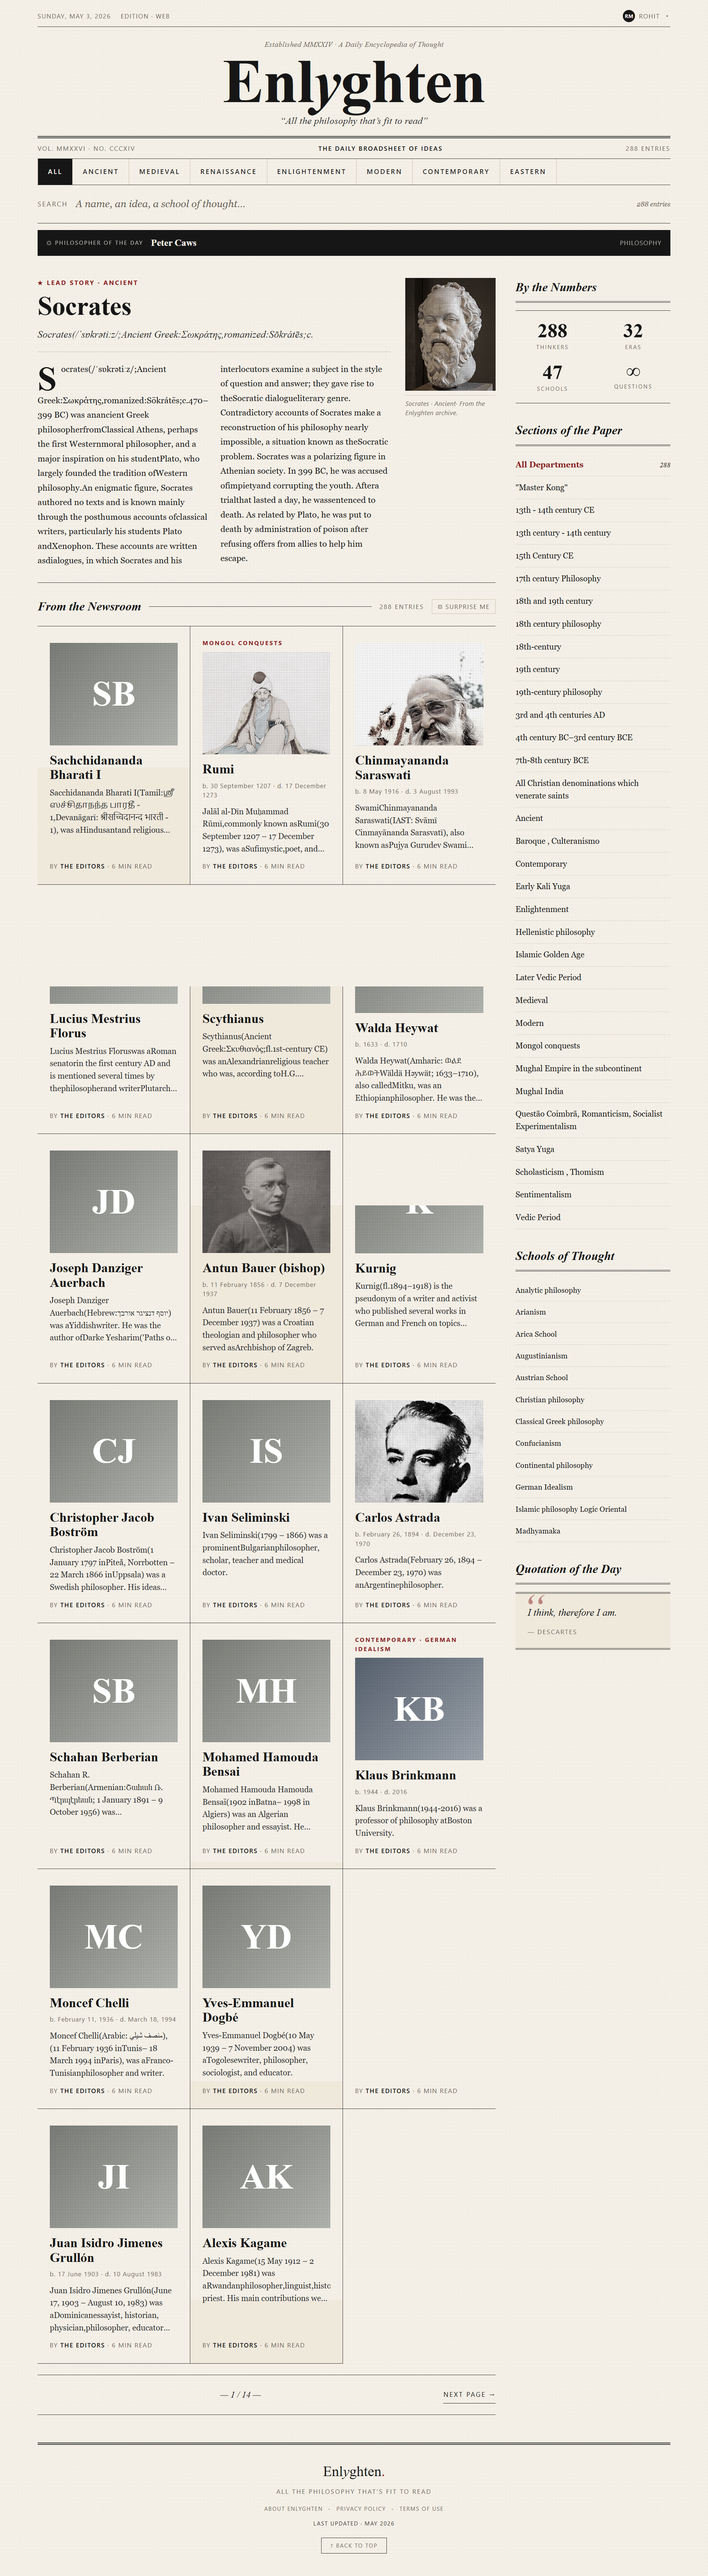
A searchable data pipeline for exploring 300+ philosophers across 25+ categories.
- Role
- Full-stack data engineer
- Timeline
- Personal project
Overview
Enlyghten turns a large collection of semi-structured Wikipedia pages into a clean, searchable knowledge product. The project combines scheduled scraping, an API, a relational database, and a Next.js interface so the dataset can be explored instead of sitting as disconnected raw pages.
The challenge
The source material was inconsistent and changed over time. The pipeline needed to collect data repeatedly, preserve a useful structure, and expose it through a UI that made filtering and discovery fast for a human reader.
The approach
I separated ingestion from presentation. A Python scraper collects and normalizes philosopher data, FastAPI exposes a typed service layer, PostgreSQL stores the structured records, and the Next.js frontend provides browsing and filtering. GitHub Actions re-runs the scraper every two days so the project stays maintainable after the first import.
Architecture
Ingestion
Python scraping and normalization for 300+ philosopher records from Wikipedia.
API layer
FastAPI endpoints provide filtered, structured access to the dataset.
Storage
PostgreSQL keeps the normalized records queryable and easy to extend.
Delivery
A Next.js interface supports browsing and category-based discovery.
Automation
GitHub Actions schedules a fresh scrape every two days.
Outcomes
- Structured data on 300+ philosophers across 25+ categories.
- Created a repeatable pipeline instead of a one-time data import.
- Delivered both a public API-backed experience and a searchable frontend.
What I learned
- Data quality and normalization decisions matter as much as the scraping code.
- Separating ingestion, storage, and presentation makes scheduled refreshes easier to reason about.